I build machine-learning systems and spend most of my time finding out where they break.
Right now that means agentic AI and document intelligence for finance and insurance: systems that read messy, high-stakes documents and have to get the answer right, show their evidence, and survive an audit. My days move between reading papers, designing evaluations, and shipping production code.
Before LLMs took over, I worked across NLP, speech, computer vision, and adversarial ML. I studied Computational Linguistics at the University of Stuttgart and have been building with ML since 2018.
Stuttgart, Germany
01
Featured projects
Production AI, public software, and research show different sides of my work.
2026 · Public application
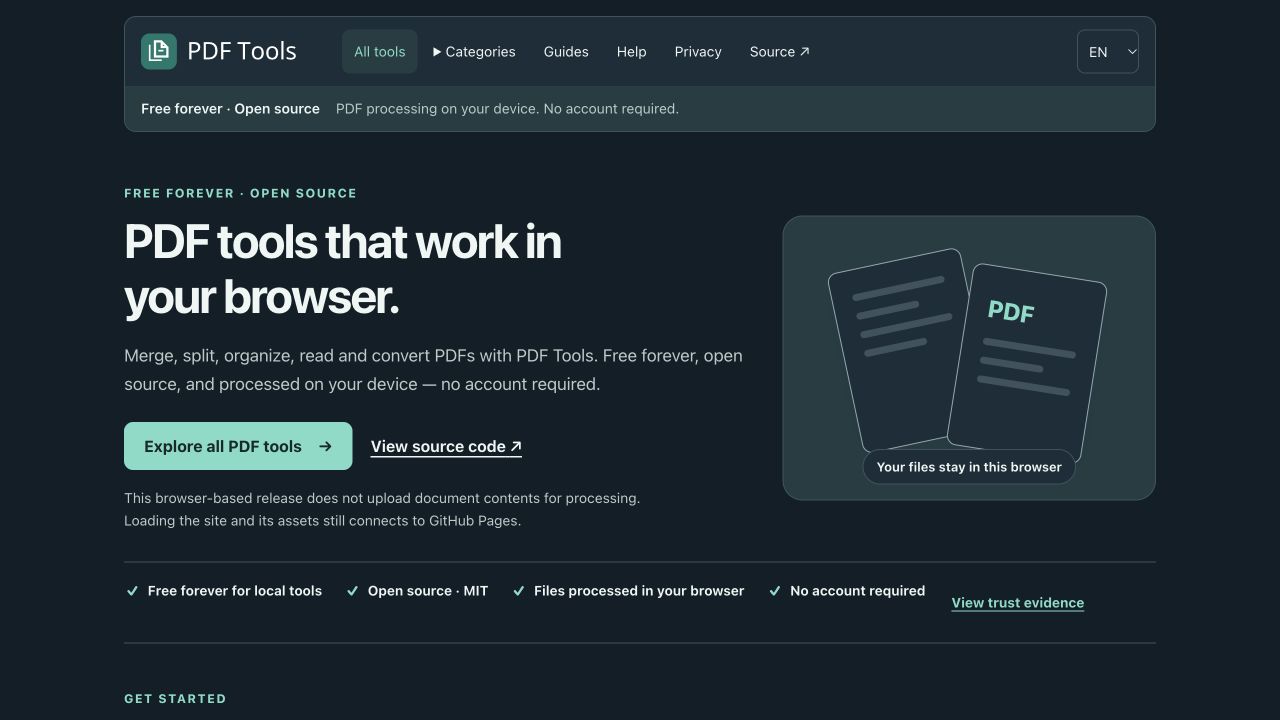
PDF Tools
Fourteen browser-based tools for merging, splitting, organising, reading, and converting PDFs. Selected documents are processed on the device; loading the application still connects to GitHub Pages. The engineering work includes independent checks of downloaded outputs and explicit limits for document features that exports may lose.
Financial and insurance documents are long, inconsistent, and expensive to get wrong. I build the pipelines that read them — OCR, retrieval, specialised agents, validation — and return structured output a human reviewer can check. The interesting problems are rarely the model; they're grounding and knowing when to hand off to a person.
Phishing domains that look like trusted ones — paypa1.com with a digit for an L — can slip past text-based filters. GlyphNet renders the domain as an image and uses an attention-based CNN to spot the visual trick. The paper reports 0.93 AUC on 4M images; the separately rendered public release contains 1.29M domain pairs.
An open question I keep coming back to: can diffusion models generate speaker embeddings that anonymise a voice without wrecking it? SpeakerDiff is the prototype for testing that. It's not a finished answer — the privacy claim needs evaluation of the full conversion pipeline — but the code and experiments are public.