Knowledge Graphs: Data Models, Construction, and Graph RAG

A knowledge graph represents entities and the relationships between them in a graph-shaped data model. Its value is not that graphs automatically contain truth or make systems explainable. The value is that identity, relationships, provenance, and domain meaning can be made explicit and queried together. That distinction matters in applied AI. A graph built from noisy documents can preserve extraction errors. A graph query can return an irrelevant path. An ontology can support valid inference from false assertions. A language model can still misread correctly retrieved facts. Knowledge graphs create useful structure; reliability comes from the evidence, controls, and evaluation around that structure. ...
March 15, 2024 · 12 min · Akshat Gupta
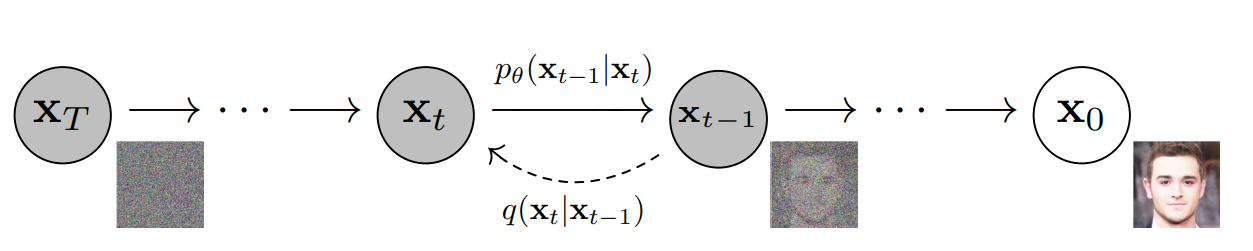
Forward noising and learned reverse denoising processes in a diffusion model

What Are Diffusion Models?

A diffusion model learns to generate data by reversing a controlled corruption process. During training, clean examples are mixed with noise at different intensities. A neural network learns what noise was added—or, in equivalent parameterizations, what clean sample or velocity produced the noisy input. During generation, the model begins with random noise and repeatedly transforms it into a structured sample. That description is simple, but three details matter: Training does not run the entire noising chain for every example. Any noise level can be sampled directly. The reverse transition is learned because the exact reverse distribution depends on the unknown data distribution. Generation is iterative. Computation within one step is parallelizable, but the denoising steps themselves are sequential. The formulation was introduced by Sohl-Dickstein et al. and made practical for high-quality image synthesis by Ho, Jain, and Abbeel. This article develops the discrete-time DDPM formulation first, then connects it to modern architectures and samplers. ...

February 15, 2024 · 9 min · Akshat Gupta

Ontologies in Knowledge Graphs: Reasoning and Validation

An ontology gives a knowledge graph an explicit, machine-readable account of a domain: the concepts that exist, the relationships between them, and the statements that follow from those definitions. It can align data from different systems, support inference, and make the intended meaning of a graph inspectable. That does not make an ontology a database schema, a data-quality checker, or a guarantee that every statement in the graph is true. Those responsibilities require different mechanisms. In particular, OWL reasoning and SHACL validation answer different questions: ...

January 15, 2024 · 11 min · Akshat Gupta

Vector Databases: Indexes, Retrieval, and Production Trade-offs

A vector database stores vectors alongside identifiers and metadata, indexes them for similarity search, and provides database capabilities such as persistence, filtering, updates, access patterns, and operational management. Its purpose is broader than running a nearest-neighbour algorithm. That distinction separates a database from a library such as FAISS. FAISS provides efficient vector indexing and search primitives. It does not, by itself, provide the complete persistence, multi-tenancy, metadata, authorisation, backup, replication, and service-management layer expected from a production database. ...

December 15, 2023 · 13 min · Akshat Gupta

Fairness in Machine Learning: Metrics, Trade-offs, and Evaluation

Fairness is not a property that can be established by checking whether one metric exceeds a universal threshold. It is a system-level question about people, decisions, benefits, harms, institutions, and the evidence used to justify an intervention. Machine-learning metrics still matter. They can reveal differences in selection rates, error rates, calibration, and performance across groups. But choosing a metric is already a policy decision: it determines which differences count as harms and which trade-offs receive attention. ...

October 15, 2023 · 12 min · Akshat Gupta